Flagship project delivers step change in text analytics capability

November 15, 2022

The HDR UK National Text Analytics Project team recently came together to share the impacts of their work and opportunities for clinical natural language processing (NLP). Rene Ndoyi, one of the attendees, describes his experience of the HDR UK National Text Analytics project symposium.


Author: Rene Ndoyi, Intern at Institute of Health Informatics


Maximizing text analytics capability for health data research: key learnings from the HDR UK National Text Analytics project symposium

On 28 September 2022, the HDR UK National Text Analytics Project team, led by Professor Richard Dobson (UCL Institute of Health Informatics; King’s College London) and Dr Angus Roberts (King’s College London), came together to share the impacts of their work and opportunities for the clinical

natural language processing (NLP) community to deliver and use new NLP tools at this HDR UK symposium.


This flagship project has delivered a step-change in text analytics capability, enabling a major shift in the UK’s ability to use research-ready, actionable, real-time electronic health records by delivering data-driven systems with potential to transform patient care. Sixty people from across HDR UK and the text analytics community attended the symposium to hear about the wide-reaching impacts of the project, learn about methods, tools and challenges for NLP and text analytics research, and discuss what the community needs to be able to access and use NLP resources for research. One of the attendees, Rene Ndoyi describes his thoughts and learning from the symposium below.


My name is Rene Ndoyi, a recent graduate of the HDR UK Black Internship Programme and intern at the UCL Institute of Health Informatics. The internship programme was such a success in my quest to develop a career in health data science. Among the many interesting projects that I was introduced to is the National Text Analytics Resource – led by Professor Richard Dobson (UCL Institute of Health Informatics; King’s College London) and Dr Angus Roberts (King’s College London).


This flagship project has delivered a step-change in text analytics capability, enabling a major shift in the UK’s ability to use research-ready, actionable, real-time electronic health records by delivering data-driven systems with potential to transform patient care. The project has built a community and brought together specialised resources that provide researchers with the tools and support to explore unstructured free text clinical data, using natural language processing (NLP) and text analytics.


Sixty people from across HDR UK and the text analytics community attended the symposium to hear about the wide-reaching impacts of the project, learn about methods, tools and challenges for NLP and text analytics research. Attendees also discussed what the community needs to be able to access and use NLP resources for research.


My internship mentor, Natalie Fitzpatrick, recommended that I attend the symposium as one of the many ways that the project brings together a community but also creates awareness of opportunities for NLP research being carried out across HDR UK.


It was very insightful and interesting to learn about the work that has been done and the success the project has earned over the past five years.


As an early career researcher who is building my skills in data science, I was keen to learn of the various tools and methods that have been developed to address the challenges of using unstructured free text data. A key piece of work is CogStack, a clinical information retrieval and extraction platform to create richer, more useful clinical information to improve healthcare. The tool enables querying data, without having to code thousands of SQL queries, based on real-time data.

Another tool I learnt about was MedCAT, which extracts information from Electronic Health Records and links it to biomedical vocabulary systems like SNOMED-CT and UMLS. Both of these tools are available for the research community to use via the Health Data Research Innovation Gateway, with the code made open source on GitHub.


Efforts to develop and apply these kinds of tools are important in tackling challenges around avoiding bias, transferability and model sharing.


The team described various ways that they are approaching this – from improving access to unstructured data for research, to developing trusted models of governance and standards. They have developed a template model sharing agreement that is being used across 10 different NHS Trusts to date, so that NLP models can be shared easily.


I also learnt that analysis of free text data can be achieved through R programming, a language I am currently learning. The idea of coding reproducible step by step workflows and frameworks is related to my internship learning experiences. Under Dr Johan Thygesen’s supervision, we are exploring development of reproducible and extensible frameworks, based on a previous study that developed a framework for Covid 19 trajectories among 57 million Adults in England.


Speakers also highlighted the importance of data governance and employing user-centred approaches. Natalie Fitzpatrick gave an interesting talk on creating a free text donated databank to develop and train NLP tools. I was fascinated to hear people’s feedback about this databank. Stakeholders, including patients and the public, researchers, clinicians and information governance and ethics experts, shared their thoughts through focus groups. There was a lot of support for the databank, but important issues were highlighted, such as the need to overcome different forms of bias, lack of generalisability, poor quality of data and patients’ ability to access their data to correct errors.


From my experiences at the symposium, I have no doubt that these efforts will harness more opportunities for improved patient care. I look forward to future meetings and opportunities to learn more about the National Text Analytics Resource project.


Share
September 24, 2026
We are delighted to welcome Srinivasan Vairavan , Director of Digital Health and AI Biomarkers at Johnson & Johnson Innovative Medicine R&D and Visiting Lecturer at King's College London , to deliver his seminar, "Precision Psychiatry through Digital Phenotyping: Lessons Learned from Three Longitudinal Studies in major depressive disorder" , as part of the EPSRC DRIVE-Health Seminar Series. Abstract: Major Depressive Disorder (MDD) remains diagnosed and monitored almost entirely through episodic, subjective self-report, limiting both clinical care and trial sensitivity. This lecture presents evidence that passively collected digital signals can objectively characterize core MDD symptom domains and track an individual's mental state continuously between clinic visits. Drawing on more than 1,000 patients across three major longitudinal cohorts — RADAR-CNS, ORBIT (NCT02489305), and CANBIND — we describe methods that translate subtle behavioral and physiological data into clinically interpretable biomarkers. Paralinguistic analysis of speech is used to quantify psychomotor retardation, while fractal signatures derived from actigraphy index depression severity and impending relapse. Building on these markers, we present a personalized, N-of-1 anomaly detection framework that fuses passive digital streams with intermittent self-report to flag elevated relapse risk at the individual level. Results support the clinical validity of this approach. Digital measures, including speech intensity, showed significant associations with clinical outcomes. The relapse prediction model achieved a balanced accuracy exceeding 71%, with a median detection lead time of two to three weeks prior to clinical onset and a low false alarm rate — a profile compatible with real-world deployment. The lecture will also address principal sources of measurement variability, including seasonal effects, and the emerging relationship between cognitive performance and digital biomarkers. Together, these findings indicate a shift from episodic subjective assessment toward objective, unobtrusive, and continuous monitoring in mental healthcare — with near-term implications for patient selection and endpoint sensitivity in clinical trials, and longer-term potential for personalized diagnosis and treatment in MDD. Seminar Series Event : "Precision Psychiatry through Digital Phenotyping: Lessons Learned from Three Longitudinal Studies in major depressive disorder" Date and Time: Thursday 15 October 2026, 13:30 – 14:30 (BST) Location: The River Room, King’s Building, 2nd Floor, Room KIN 227, Strand Campus Attendance: Mandatory for all DRIVE-Health students; a calendar invitation has already been sent. Registration: Alumni and the wider King's College London research community are welcome - no booking required. Biography Srinivasan Vairavan , PhD, is Director of Digital Health and AI Biomarkers within Neuroscience Data Science and Digital Health at Johnson & Johnson Innovative Medicine R&D, and a Visiting Lecturer in the Department of Biostatistics and Health Informatics at the Institute of Psychiatry, Psychology and Neuroscience, King's College London. He has over 15 years of experience building and scaling AI, machine learning and advanced analytics capabilities across pharma and healthcare, with prior roles at Proteus Digital Health and Philips Research. His work translates large-scale clinical, digital health, molecular and EHR data into regulatory-grade endpoints, including engagement through FDA Type C meetings and EMA Qualification Advice, and co-development of the industry-wide V3+ framework. He leads and contributes to major international consortia including RADAR-CNS, RADAR-AD and AMP-SCZ. He holds patents in relapse prediction in major depressive disorder and speech-based detection of cognitive decline, sits on the editorial board of BMC Digital Health, and serves on the DRIVE-Health advisory board.
July 28, 2026
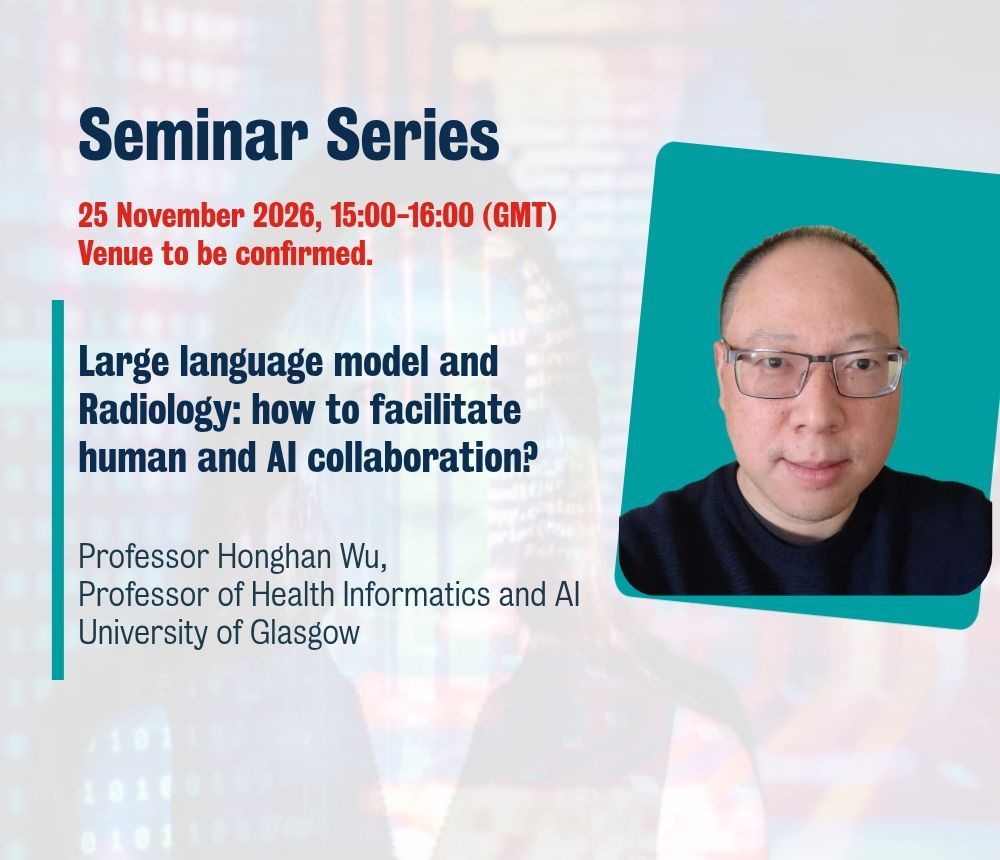
We are looking forward to welcoming Professor Honghan Wu, Professor of Health Informatics and AI at the University of Glasgow, who will deliver his talk “Large language model and Radiology: how to facilitate human and AI collaboration? " as part of our Seminar Series. Abstract: In this upcoming talk, Professor Honghan Wu explores the essential shift from viewing AI as a potential replacement for radiologists to recognizing it as a critical collaborative partner. Moving beyond basic tasks like detection and triage, the presentation highlights how AI can address practical clinical "pain points," such as reducing automated protocoling time by up to 60% and decreasing the time spent communicating with providers and patients by 30%. Professor Wu will present recent research on using knowledge-retrieval and Large Language Models for clinical report error correction and generation. The session concludes with an examination of the real-world deployment lifecycle, discussing the challenges of monitoring the over 700 FDA-cleared radiology AI devices currently in practice Seminar Series Event : “Large language model and Radiology: how to facilitate human and AI collaboration?" Date and Time: Thursday 25 November 2026, 15:00 – 16.00 hrs (GMT) Location: Venue to be confirmed. Attendance: Mandatory for all DRIVE-Health students; a calendar invitation has already been sent. Registration: Alumni and wider King's College London research community all welcome - please email drive-health-cdt@kcl.ac.uk to let us know if you would like to attend. Biography Honghan Wu is a Professor of Health Informatics and AI, based in the School of Health and Wellbeing of the University of Glasgow, where he leads the research theme of data science and AI. Prof Wu is a co-director of Health Data Research Scotland. He also is an honorary professor at Hong Kong University, an honorary associate professor at Institute of Health Informatics, UCL, and a former Turing Fellow of The Alan Turing Institute, UK's national institute for data science and artificial intelligence. Prof Wu holds a PhD in Computing Science. His current research focuses on machine learning, natural language processing, knowledge graph and their applications in medicine.